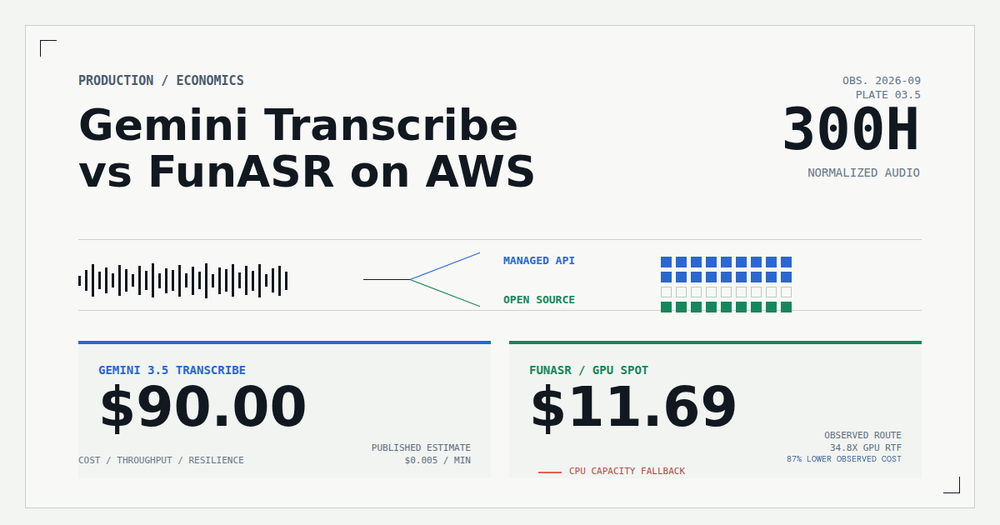
- The Three-Phase Transcription Pipeline A production podcast transcript is not produced by one model call. The pipeline behind these measurements has three stages: Phase 1: VAD, speech recognition, punctuation, timestamps, and speaker diarization. Phase 2: speaker identity verification and label correction. Phase 3: …
Read More about Gemini Transcribe vs FunASR: Production Economics
Two recordings sat on my disk waiting to be turned into searchable text. A 4-hour 13-minute discussion from a TGO founders' group — eight speakers, Chinese, Zoom audio. A 1-hour 8-minute podcast episode (屠龙之术 Vol.94 × 知本论) where two hosts spent the whole hour dissecting OpenClaw — its positioning, the AI-agent …
Read More about Transcribing Long Podcasts and Meetings with FunASR

